
Back in March I wrote paper with a few colleagues about AI’s place in peer review. The preprint is here, and I wrote a short post about it here.

Now there’s some irony here. A good part of the introduction motivates the paper’s proposal by bemoaning the fact that the peer review machinery is buckling under the weight of an ever increasing number of submissions (surely driven by AI in part). The irony here is that this paper, which proposes a partial solution to the problem of overburdened peer review, has been stuck in peer review for over 6 months because at least one of the reviewers wasn’t available or responsive after we turned around a revision in <1 week.
Paul Bloom, who edits Behavioral and Brain Sciences, recently wrote in the Chronicle that the interesting question to ask about AI in peer review is how well it does against the available alternative, the median reviewer (who is tired, overburdened, doing hard work for free because P&T expects and rewards it, etc.). He proposed an experiment: collect human and AI reviews of the same papers and have people compare them.
It would be useful to run some simple experiments: Ask researchers, scholars, and editors from different fields in the sciences and humanities to compare human reviews and AI reviews across a range of dimensions.
Gary King and Steven Worthington at Harvard’s Institute for Quantitative Social Science have now run that experiment. The new paper is called “AI Article Reviews Dominate Human Peer Reviews at Their Best: Evidence and Policy Choices.” I don’t like the word choice of “dominate,” but put that aside for a moment and at least consider the top line finding:
The human reviewers lost on every measure the authors could construct.
Here’s figure 1 from the paper.
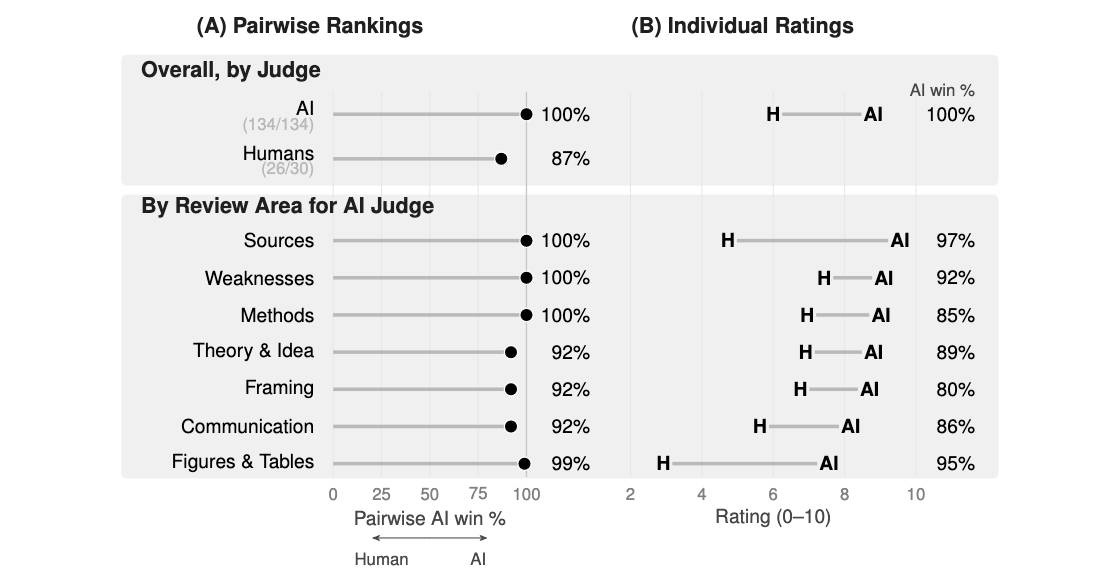
In a way the design actually favored human reviewers. The 124 papers came from rapidPeer, a service at Harvard that pays outside experts to write long, constructive, double-blind reviews of faculty drafts before journal submission. Authors rated these reviews highly, and former journal editors told King and Worthington they were among the best they had seen. Claude Opus 4.8 reviewed each paper with the same reviewer instructions. GPT-5.5 judging each pair blind preferred the AI review every time. Maybe that’s not unexpected. You’d think that AI likes AI’s writing. Three former journal editors, who didn’t know one review in each pair came from an AI model, picked the AI review in 26 of 30 judgments. The AI reviews made about a third as many incorrect claims about the manuscripts as the human reviewers did. The AI reviews cited no fabricated sources. The AI reviews also kept their advantage when the comparison was restricted to reviews of similar length or when the human reviews were rewritten in AI style.
So back to that paper I wrote with Agnieszka Swiatecka-Urban and Arjun Krishnan arguing for AI as a quality-control and consistency tool in peer review, with humans keeping the judgments about novelty and feasibility. For the part of review that helps authors improve a paper, King and Worthington’s results make that division of labor look maybe a little too conservative! The authors are careful to say their results don’t address the other job of review, which is helping editors decide what to publish. Maybe this is where the human role now belongs. Whether a sound paper is important enough for a given journal is a judgment about what a field should read, and I think a person who’s accountable has to make that decision, not an AI.
I think that leaves us as academics in a place where we need to really think about how the practice of science should adapt to what AI can already do now and where it’s going. And we need to do so fast. King and Worthington sketch one version. Journals could publish an official review prompt, and authors iterate against it and submit the final AI review with a letter explaining where they disagree.
Third, journals could require an AI review, generated by the journal’s official AI prompt, be submitted with the paper, as well as a letter from the author explaining any remaining open questions or disagreements with AI.
The editor could read that dossier alongside a second AI review from a prompt kept private, calls in human reviewers for hard cases, with the editor ultimately making the decision. It is close to the half-serious proposal in Bloom’s essay, down to the public prompt.
You can start before any journal adopts it. Before your next submission, give the manuscript and the journal’s reviewer guidelines to a current frontier model,1 and draft the response letter you would write if a human had raised the same points. Bloom tried this on a paper he had already submitted to a top cognitive science journal. Claude recommended rejection and asked for two more studies, and he wrote that he wished he had run it first.
Addendum: AI review on this paper about AI reviews
The authors noted in a disclosure they used an enterprise account (frontier) AI in this paper, but didn’t really say how. That’s fine, I’m skeptical of AI disclosures anyway. The authors already ran this through an online AI, and the paper is publicly available online anyway. So I think it’s fair game to run this paper through an AI yourself.
Because the authors seem to frequently submit to PNAS, and because the paper clocks in at just under the 4,000-word limit for a PNAS research report, I prompted Opus 5.5 to review this paper as if it were being submitted to PNAS. The full review along with the detailed prompt I used to review this paper are both here.
The review in this case pointed out some real limitations in design, analysis, and called out blatant overstatement of the conclusions given the limited results. Read the full AI review here. Preview below.

Obviously do so on a paid account where you have training or “improve the model for everyone” turned off. See here for more. Or maybe don’t do it at all if there’s something so seriously groundbreaking in your manuscript that you wouldn’t want any eyes, human or machine, to see it before it’s peer reviewed and published.